 PAID10:28
Plays here · Open on youtube ↗
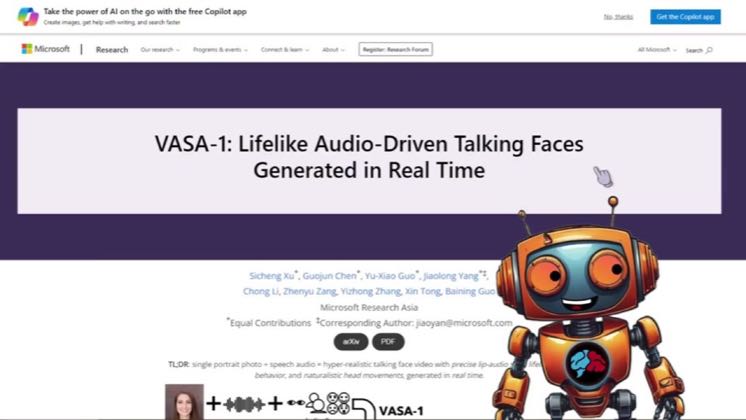
“VASA-1: Lifelike Audio-Driven Talking Faces Generated in Real Time”
The opening line · 0:00 · move: reveal
Compares one control portrait across Hedra, SadTalker, HeyGen, D-ID and DreamTalk, then builds a two-character singing clip through Suno, 30-second audio splits, Stable Diffusion portraits, white-background prep, Hedra generation and detailed CapCut chroma-key compositing, including creature and green-screen failure limits.
@AI Controversy · 29.4K followers · 1 of 30 recent posts mention Hedra · creator page →
- 0:00this AI tool brings their pictures to life like never before. You can even make your fictional
- 0:04characters speak with stunning realism. So, how realistic candy's talking photo animations really
- 0:09be? Check it out. Introducing Hydra, the best and most accurate talking AI photo out right now,
Lead with a believable singing character, then credit or demonstrate the image-plus-song workflow that turns a static portrait into a music-video performance.
AI music-video makers and avatar educators using Hedra as the lip-sync performance layer · 21 creators · 21 posts
Open the full playbook →
this post · other creators who ran it
@AI Controversyyoutube · 29.4K followers · median 2.1K views · n=60best post11.5K5.5×views · for HedraUnknown The source links only to the creator's own Hedra article and states “Affiliate links may be included in our content” without a creator-specific Hedra code or tracking parameter; commercial relationship remains unverified — https://www.youtube.com/watch?v=a06V5r7KEnoOpen creator →Views and likes are public counts at capture time. The multiple compares this post with the creator’s own recent median, not a claim about what caused its reach. Read the methodology →