Loading the library…
 PAID4:43
The anchor — the post this playbook is read from.
Open the post page →
Playbook
Turn a Flora image prompt into a connected video
Flora creators write an image prompt, generate the image, and pass it into a connected video node for animation.
Who runs it Three non-owned creators: Le Kpakpato de l’IA, Escapism, and Tech with Tas.
72.1Kviews tracked · 3 posts3creators ran it66.3Kbest post
affiliate2 of 3 posts say unknown
Not dissected yet. The captured frames and transcript are the available evidence.
The script57 lines · 4:43 · @Tech with Tas for FLORA
- 0:00I'm gonna be real with you, if you're creating content in 2025 and still bouncing between
- 0:05Chachi PT Mid Journey, Canva Google Docs and 5 other tabs, you're not multitasking, you're
- 0:11just suffering efficiently.
54 more linesmembers read and copy every script on the site
These moves recur across the cited posts. Wording and execution vary; this is not one combined video timeline.
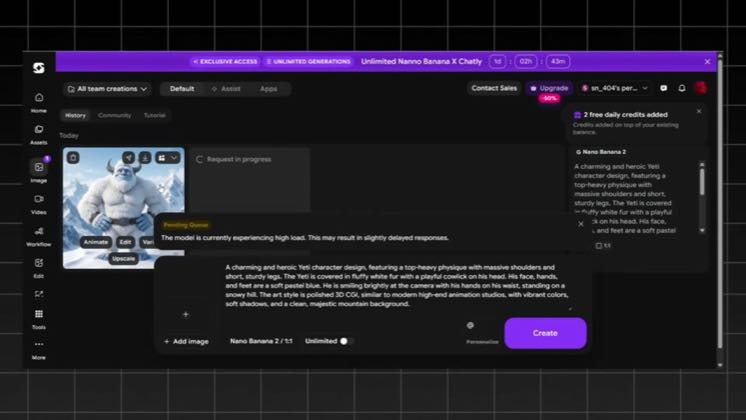
- Enter an image prompt on the canvas
Read the source quotes
donc le petit plus là je le tire et là je vais écrire en fait faire porter cette robe là à un mannequin donc j'ai crié mon prompt ce que je veux donc j'ai pris le petit plus qui était à côté de l'image je l'ai tiré et là j'écris mon prompt
Open the source post →The way I did that is I created a new text node like that, and I typed out, described the image without any text logos or buttons with the red car and background only.
Open the source post →I double click the canvas and open a text node, I type, "A fluffy orange cat sitting on a wooden desk next to a laptop." Flora instantly enhances the prompt, that's my base idea.
Open the source post → - Generate and inspect the image result
Read the source quotes
donc fait porter cette robe là un mannequin dans un style shooting, cadre, photo studio etc donc j'écris bien mon prompt ce que je veux et je charge voilà ça nous donne une mannequin très belle mannequin
Open the source post →And then I generated an image using CDream 4.5, new node, and it uses that output of the text node to create the new image.
Open the source post →Next I add an image node, choose a style, set the aspect ratio, pick a model on the free plan, I'm using flux, here's where it gets good, connect the text node to the image node, the prompt flows automatically, hit generate, about 30 seconds later, boom, clean image,
Open the source post →
This playbook belongs to a structure shared across brands. Its member videos count toward each structure’s total. Open a structure to compare the grouped playbooks.